Ask the major AI assistants what DeepSeek V4 is and you get a different answer from each, most of them wrong. With web search switched off, ChatGPT calls it "rumors and roadmap speculation," Gemini dates itself to 2025 and says no such model exists, and Claude declines to answer. Turn search on and it barely improves: ChatGPT lands on the April preview announcement and concludes V4 has not left the preview stage, which stopped being true five weeks before this sentence was checked. It happened again just weeks later: DeepSeek replaced its own Flash model on September 10, 2026, and most of the web still describes the model that existed the day before.
In one line: DeepSeek V4 is Chinese lab DeepSeek's current open-weight model family, now a fast, vision-capable Flash model (V4.1 Flash, from September 10) and a flagship Pro, generally available since August 2026 under an MIT license. Here is the fuller version, checked against primary sources as of September 2026: what DeepSeek V4 actually is now that it has shipped and been through a full generation of Flash already, what it genuinely costs once you account for the parts the sticker price hides, whether the benchmark claims survive an independent look, and whether you can put it anywhere near real work. Where a number is DeepSeek's own claim rather than an outside measurement, we say so, because on a model this new that distinction is most of the story.
What DeepSeek V4 Is (and What Changed at GA, Then Again on September 10)
DeepSeek V4 is the current family of open-weight models from DeepSeek, the Chinese lab in Hangzhou. Flagship V4-Pro reached general availability on August 13, 2026 after a months-long preview that opened on April 24, and it is still DeepSeek's model for the hardest reasoning and coding work. The Flash tier has moved twice in that same window: a mid-cycle refresh (V4-Flash-0731) that landed just before Pro's GA, on July 31, then a full architecture change, DeepSeek-V4.1-Flash, on September 10, 2026, which retired V4-Flash-0731 outright. If you read an explainer that still calls V4 a preview, or that describes Flash without mentioning V4.1, it is out of date, and so is DeepSeek's own V4-Pro model card, which still carries preview wording (more on that under the benchmarks).
V4 is not a single model. DeepSeek-V4-Pro is the flagship, built for hard reasoning, agentic work, and demanding code, a 1.6-trillion-parameter mixture-of-experts model with 49B active parameters. DeepSeek-V4.1-Flash is the fast, cheap workhorse for everything else, a 552-billion-parameter MoE model (with a further 196B parameters in what DeepSeek calls its Engram component) using a new causal encoder-decoder architecture, with only 8B parameters active on the input side and 16B on output. Both models ship a one-million-token context window and up to 384K tokens of output, and both are released as open weights under the MIT License, so you can download and run them yourself.
Several things changed when V4 moved from preview to GA, and more changed again on September 10. It retired the old deepseek-chat and deepseek-reasoner model names on July 24. It refreshed Flash to DeepSeek-V4-Flash-0731 on July 31. On August 16, 2026 it made good on months of warnings about a "significant" price increase, replacing the flat all-day rate with the peak/off-peak split covered below. Then on September 10 it retired V4-Flash-0731 entirely, along with the experimental V4-Flash-Vision-Exp, and replaced both with V4.1 Flash at a new API id (deepseek-flash) and a lower price. That same release announcement said DeepSeek was "phasing out V4-Pro," with every deepseek-v4-pro request set to reroute to V4.1 Flash starting 04:00 UTC on September 14. Its API changelog then reversed that, "in response to user demand," and days after that cutover the live pricing page still lists V4-Pro as its own separately priced model, so treat Pro as continuing, not retired, until DeepSeek says otherwise.
The clearest limit that just changed: V4 used to be text in, text out, full stop, with no image, audio, or video input on the mainline models. That gap against ChatGPT, Gemini, and Claude is now half closed. V4.1 Flash has native vision, the first DeepSeek Flash-tier model that reads images, folding in what the experimental Vision-Exp build was testing. V4-Pro still has none. If your work needs a model to read a screenshot or a chart and you are picking between DeepSeek's own tiers, that now argues for Flash over Pro, which used to be true only for price.
The V4 Lineup: Flash vs Pro
Flash and Pro are not a scaled-down copy of its bigger sibling; they are different mixture-of-experts configurations at very different price points, and Flash just changed architecture entirely. The rule of thumb about which to use also shifted after GA: on DeepSeek's own numbers, the new Flash is now strong enough to beat the Pro it costs a fraction of.
| Model | Size (total / active) | Best for | API price (per 1M tokens) |
|---|---|---|---|
| V4.1-Flash | 552B + 196B / 8B in, 16B out | Chat, extraction, classification, summarization, high-volume agent loops, most coding, now image input | $0.15 in / $0.60 out off-peak, up to $0.30 / $1.20 at peak |
| V4-Pro | 1.6T / 49B active | Hard reasoning, complex multi-step analysis, the most demanding code | $0.66 in / $1.98 out off-peak, up to $1.32 / $3.96 at peak |
Both are mixture-of-experts designs, which is why the active parameter count is a fraction of the total: the model holds a huge number of parameters but switches on only a small slice for any given token. That is the trick behind the low running cost. V4.1 Flash pushes the idea further with an asymmetric split, only 8B parameters active when it reads your prompt and 16B when it writes the answer, on top of a causal encoder-decoder design that separates the two jobs architecturally rather than running one dense stack for both.
The default is Flash for almost everything. It is cheap enough that at normal volumes the bill is a rounding error, and independent measurement backs up DeepSeek's own claim that the September refresh is a real step up: Artificial Analysis scores V4.1 Flash at 40 on its Intelligence Index (its "Reasoning, Max Effort" setting), ranking it 6th among the 113 large open-weight models it tracks and well above that group's median (18). Reserve Pro for the work that genuinely needs it, hard reasoning and the most demanding code, where the quality gain is worth the roughly 3 to 4 times higher token cost (3.3x on output, 4.4x on input, Flash got cheaper on September 10, widening the gap). If you cannot tell whether a job needs Pro, it probably does not; start on Flash and move up only when you hit a wall.
The September 10 change matters more than the July 31 refresh did. DeepSeek-V4-Flash-0731, the build from that earlier refresh, is what the wave of "Flash just got better" reviews from July and August were reacting to; a high-reasoning variant of it placed seventh overall, and third among open-weight models, on the Frontend Code Arena leaderboard at the end of July. V4.1 Flash retires that build entirely rather than tweaking it further, and DeepSeek's own benchmark claims put it ahead of V4-Pro, not just ahead of the prior Flash. On coding benchmarks DeepSeek published in its own release announcement, reported by MarkTechPost, V4.1 Flash scored 90.6 on Terminal-Bench 2.1 against V4-Flash-0731's 82.7, and 74.2 on the DeepSWE v1.1 benchmark against 54.4 before, edging out both Claude Opus 5 (89.1 / 74.0) and GPT-5.6 Sol (88.8 / 73.0) on those two tests specifically. The same table has a third benchmark, Terminal-Bench 4.0, where V4.1 Flash does not win (31.2, against Opus 5's 51.8 and GPT-5.6 Sol's 39.9), worth knowing before you read "edges out Claude and GPT-5.6" as a blanket claim. Treat all of it carefully: these are numbers DeepSeek chose to publish about its own model against named rivals, not an outside lab's independent re-test the way CAISI's numbers below are. If you benchmarked Flash before September 10, benchmark it again; the model behind the name, whether you call it deepseek-flash or the legacy deepseek-v4-flash alias, has changed twice now.
The 1M Context Window Is Real, but It Is Lossy
The headline feature is the one-million-token context window, and the interesting part is how DeepSeek made it affordable rather than the number itself. V4 uses a hybrid attention design, combining what DeepSeek calls Compressed Sparse Attention and Heavily Compressed Attention. At the full million-token setting, the technical report puts V4-Pro at roughly 27% of the per-token inference compute and about 10% of the KV-cache memory of the previous generation, DeepSeek-V3.2. That is a real engineering win, and it is why V4 can quote a 1M window at a price a dense model could not reach.
There is a second change agent builders care about: in tool-using conversations, V4 preserves its reasoning across user turns instead of dropping it when a new message arrives, so multi-step workflows hold together better. One caller obligation comes with it: you have to pass that earlier reasoning back on each request, or the API rejects the call.
Here is the catch the spec sheet leaves out. A window that is cheap to run behaves as if it is lossy, and you feel it as the model "ignoring" things. Developers running V4 on large inputs report, consistently, that it seems to forget instructions placed near the top of a long prompt, and some say the drop-off starts well before the million-token ceiling. DeepSeek has not published a per-position retrieval breakdown, and the technical report does not call the compression lossy, but the most plausible explanation is the same attention compression that makes the window affordable.
Either way, the fix is a workflow habit, not a bug report. Put your load-bearing instructions near the end of the prompt, not buried at the top, and repeat any constraint that absolutely must hold. Treat the 1M window as a large working memory that is strong at "find the relevant passage" retrieval and weaker at holding a rule you stated tens of thousands of tokens earlier. Used that way, the context window is a genuine advantage; trusted blindly, it is where V4 disappoints people.
How Good Is It, Really?
DeepSeek's own numbers are strong. Its V4-Pro model card, the same one that still labels V4 a preview, reports 80.6% on SWE-bench Verified, 93.5% on LiveCodeBench, and 90.1% on GPQA Diamond, and it frames its knowledge results as an open-source record. Those are worth knowing. They are also vendor-reported, on a high-effort "Max" setting, and they are exactly the numbers you should check against someone independent.
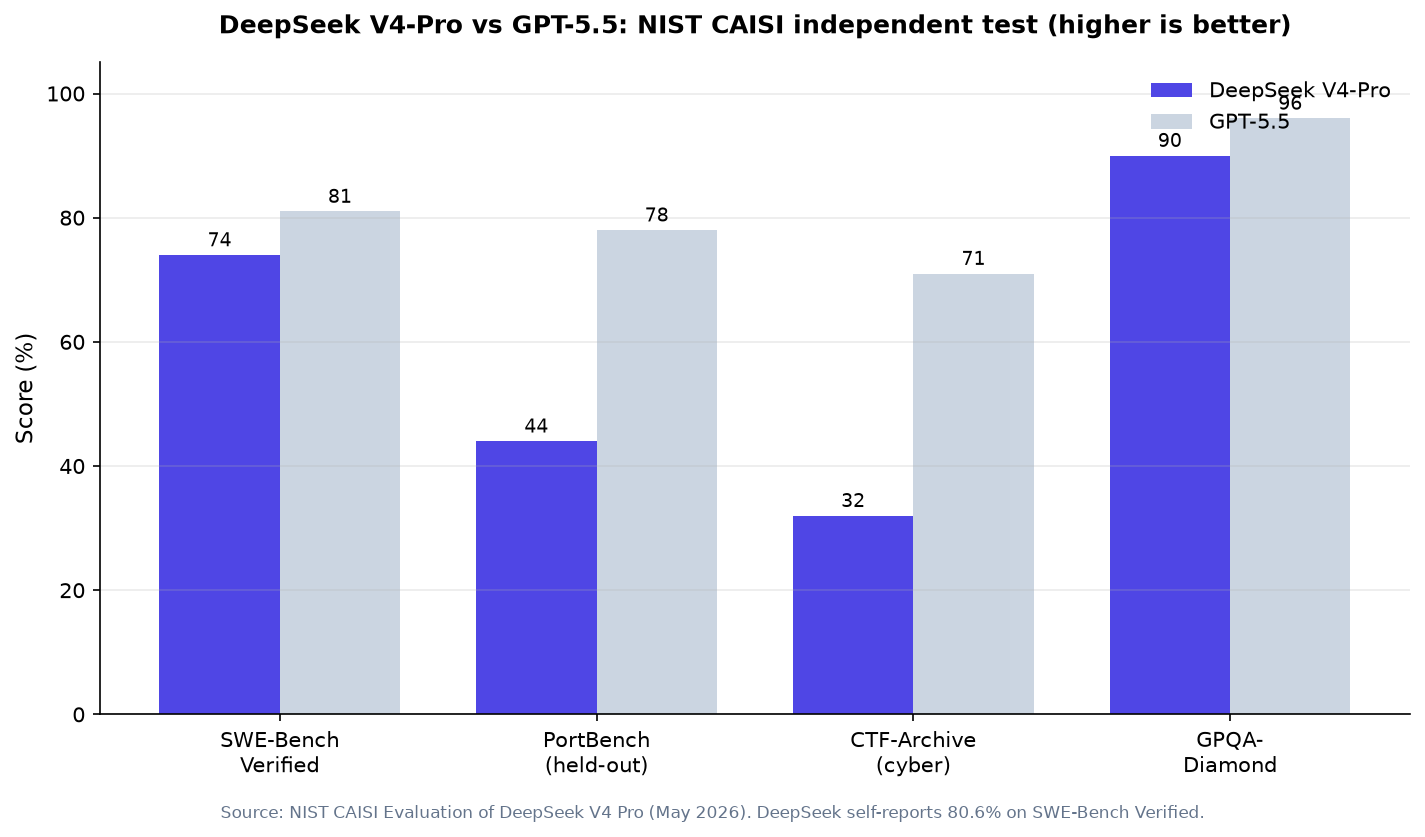
Independent evaluations tell a more grounded story, and a moving one: Artificial Analysis, which runs its own suite, currently places V4-Pro at an Intelligence Index of 36, ranking it 7th among the 113 large open-weight models it tracks, above that group's median (18) but not at the frontier; that score has drifted down since V4-Pro's original measurement as Artificial Analysis added and re-scored more models, a reminder that an Index snapshot is only current as of the day you check it. V4.1 Flash scores higher, 40, and ranks 6th of the same 113, both checked live September 2026, meaning on Artificial Analysis's own current numbers the cheaper Flash tier actually outranks Pro: independent confirmation of the vendor's own "V4.1 Flash beats V4-Pro" claim, not just a close-but-not-quite result. The US government's AI standards body, CAISI, went further on V4-Pro specifically, re-running DeepSeek's headline benchmarks and adding held-out ones of its own.
| Benchmark (CAISI test) | DeepSeek V4-Pro | GPT-5.5 |
|---|---|---|
| SWE-Bench Verified | 74% | 81% |
| PortBench (held-out coding) | 44% | 78% |
| CTF-Archive (cybersecurity) | 32% | 71% |
| GPQA-Diamond | 90% | 96% |
A couple of things jump out. First, CAISI measured V4-Pro at 74% on SWE-bench Verified, against the 80.6% DeepSeek publishes, and stated plainly that "DeepSeek V4 scores better on DeepSeek's self-reported evaluations than on CAISI evaluations." That is the vendor-benchmark gap in one sentence. Second, CAISI's overall read is that V4's capabilities lag the frontier by about eight months, with the widest gaps on held-out coding and cybersecurity, where training-data contamination cannot inflate the score.
A couple of caveats keep this fair. CAISI's math results run the other way, with V4-Pro at 97% on OTIS-AIME-2025, near parity with the US models. And CAISI ran its tests back in April, on the preview build, not the GA model; DeepSeek's own preview-to-GA numbers show sizable gains from re-training alone, so part of the gap is likely build drift rather than pure inflation, and nobody has yet published an independent re-test of the shipped model.
None of that makes V4 bad. On cost-per-task, CAISI compared it against GPT-5.4 mini, the nearest cheap US model, and found V4 ran cheaper on five of seven benchmarks but anywhere from 53% less to 41% more expensive depending on the task, a direct illustration of the thinking-token tax covered below. An independent scored test by coding-tool maker Kilo put V4-Pro at 77 out of 100, between Claude Opus 4.7 at 91 and Kimi K2.6 at 68, though that test predates the current Claude and Kimi flagships.
The honest summary: V4 is a frontier-class model on price and a near-frontier model on capability, strongest on math, reasoning, and long-context retrieval, and clearly behind the closed leaders on the hardest real-world coding, cybersecurity, multimodal work, and the longest agentic loops. If a page tells you it simply beats GPT-5.5 and Claude, it is selling the vendor's numbers, not the measured ones. That caution applies doubly to V4.1 Flash: it shipped September 10, 2026, too recently for a CAISI-style independent re-test of its own vendor-reported coding benchmarks, so its outperforms-Pro claim rests on DeepSeek's own numbers plus one independent Intelligence Index score, not the same depth of outside scrutiny V4-Pro has had months to accumulate.
What DeepSeek V4 Really Costs
The web and mobile apps are free. The money question starts on the API, and this is where V4's reputation as "the cheap one" is earned. Here are the current per-million-token rates. For a fuller cost breakdown, see our DeepSeek pricing guide.
| Model | Input (cache miss) | Input (cache hit) | Output |
|---|---|---|---|
| V4.1-Flash, off-peak | $0.15 | $0.003 | $0.60 |
| V4.1-Flash, peak | $0.30 | $0.006 | $1.20 |
| V4-Pro, off-peak | $0.66 | $0.022 | $1.98 |
| V4-Pro, peak | $1.32 | $0.044 | $3.96 |
A few catches separate that sticker price from your actual bill.
Flash was repriced twice, and Pro almost got folded into it. On August 16, 2026, DeepSeek replaced its flat all-day rate with the peak/off-peak split shown above, applying it to both models: peak hours (01:00-04:00 and 06:00-10:00 UTC, Monday to Friday, with weekends billed at off-peak) bill at exactly double the off-peak rate across every column. Then on September 10, 2026, the new V4.1 Flash architecture replaced V4-Flash-0731 outright at a lower price than the August rate, while V4-Pro's price stayed put. The same day, DeepSeek's release announcement said it was "phasing out V4-Pro" with a September 14 reroute to Flash, and its API changelog reversed that "in response to user demand." Net effect: Flash got cheaper, Pro survives for now at its old price, and the gap between them widened.
Thinking mode is on by default, and it bills at the output rate. Before it answers, V4 generates internal reasoning tokens, and those count as output even though you never see them. A short reply can quietly produce thousands of billed tokens first. If your bill is higher than the sticker suggested, this is almost always why. Turn thinking off for routine work (classification, extraction, short replies) and leave it on only where the reasoning earns its cost.
Cache hits are where the real economics live. When the start of a request matches something processed recently (a reused system prompt, a document you keep sending), those tokens bill at the cache-hit rate, dropping Flash input from $0.15 to $0.003 off-peak (or $0.30 to $0.006 at peak), a roughly 98% discount. Caching is automatic and free; you do not mark anything as cacheable, you just keep the stable part of your prompt at the front. Structure prompts to reuse a common prefix, and the same workload can cost a fraction of the headline number. There is also no separate long-context surcharge, so a million-token prompt bills at the same per-token rate as a short one at whatever time it runs.
How to Access V4: App, API, or Self-Host
There are a few ways in, and the cheapest is not always the obvious one.
The free web and mobile app at chat.deepseek.com gives you the full V4 chat with web search, no payment. The direct API is the cheapest paid route and the one to build on. OpenRouter and other resellers are convenient, but they route to third-party hosts whose rates differ from DeepSeek's own, so a price you see there may not match DeepSeek's. If cost is the priority, go direct, though DeepSeek's own API can be capacity-constrained under load, which is part of why the resellers exist.
If you build on the API, migration is the thing that will bite you, and it has happened twice. The original model names, deepseek-chat and deepseek-reasoner, retired on July 24, 2026 at 15:59 UTC, and code that still calls them fails. Their July replacements, deepseek-v4-flash and deepseek-v4-pro, plus the later experimental deepseek-v4-flash-vision-exp (added August 21), were folded into the new deepseek-flash on September 10, 2026, but more quietly: deepseek-v4-flash and deepseek-v4-flash-vision-exp are, in DeepSeek's own wording, "temporarily routed" to the new model at the new price, not permanently kept. deepseek-v4-pro was not part of that fold-in and did not change.
| Old name (retired) | Call this instead | What it maps to |
|---|---|---|
deepseek-chat | deepseek-flash | Flash, non-thinking mode |
deepseek-reasoner | deepseek-flash | Flash, thinking mode |
deepseek-v4-flash (temporarily routed) | deepseek-flash | Now routes to V4.1 Flash, billed at V4.1 Flash's lower price |
deepseek-v4-flash-vision-exp (temporarily routed) | deepseek-flash | The experimental vision build is retired; native vision now ships in V4.1 Flash by default |
The drop-in swap has two catches now, not one. First, deepseek-reasoner was never the Pro-tier reasoning model: before its July 24 retirement it mapped to Flash in thinking mode, not to Pro, and that distinction carries forward today: deepseek-flash's thinking mode is not Pro-level reasoning either. If you want Pro-level reasoning you have to call deepseek-v4-pro explicitly. Second, since September 10, code still pointed at deepseek-v4-flash is not running the model you last tested against, it is silently running V4.1 Flash, a different architecture with native vision, at a lower price. That is a strict upgrade for most workloads, but if you have output parsing or evals tuned to the old model's quirks, re-test before you assume nothing changed.
Self-hosting is the real escape hatch, with a bigger hardware asterisk than before. Because the weights are MIT-licensed, you can run V4 on your own machines, which is the cleanest answer to any data-residency concern. In practice, V4-Pro at 1.6 trillion parameters is out of reach for individuals and hard even for well-funded teams; it wants a multi-GPU server with hundreds of gigabytes of memory even when quantized. The Flash tier used to be the easy self-host target, back when it was V4-Flash-0731 at 284 billion parameters. V4.1 Flash, the model that replaced it, is a meaningfully bigger download: 552B backbone parameters plus 196B more in its Engram component, with reports putting the full downloadable weight set around 510GB, roughly three times V4-Flash-0731's footprint, even though only 8B to 16B parameters are active per token at inference time. The low active-parameter count keeps inference compute cheap once the weights are loaded, but you still need to hold the whole model in memory or fast storage to load it at all, so V4.1 Flash is a harder self-host than the Flash tier used to be, not an easier one. Plan for a high-memory multi-GPU node served with vLLM or SGLang rather than the llama.cpp or LM Studio hobbyist path, and expect quantized single-GPU setups to be tighter than they were on the old Flash. If you have run Kimi K3 locally, the constraints will feel familiar, just scaled up.
Can You Use It at Work?
This is the question that decides most professional adoption, and the answer is genuinely "it depends," not a yes or a no.
If you use DeepSeek's hosted API or app, your prompts go to servers in China. For many enterprises, government contractors, and regulated industries, that alone is a hard stop, and plenty restrict it outright. That is a routing and jurisdiction decision, separate from anything about the model's quality.
There is a middle route the open weights make possible: buy V4 from a Western host. Microsoft's Azure AI Foundry, Fireworks, and Together all serve DeepSeek's Flash and Pro tiers from US infrastructure, so your prompts never touch DeepSeek's servers and you get an enterprise contract and a data-residency commitment without owning a GPU cluster (whether each host has already picked up the September 10 V4.1 Flash weights specifically is worth confirming directly with the host, since MIT-licensed open weights typically take Western hosts a few days to add after a release). You pay a margin over DeepSeek's direct rates; that is the price of jurisdiction.
Or self-host. Because V4 is MIT-licensed, a team that cannot send data anywhere it does not control can run the model on its own infrastructure, so prompts never leave the building and the hosted app's logging and terms do not apply. One caveat self-hosting does not fix: political refusals and topic-alignment are trained into the weights, so a self-hosted V4 still dodges or skews on sensitive questions the way the hosted one does. Self-hosting answers the data-residency question, not the will-it-answer-straight one. The wider trust picture, including how DeepSeek handles data on its own servers, is covered in our DeepSeek explainer.
DeepSeek V4 vs the Competition
The framing that keeps people straight is that V4 is a model you can download, while ChatGPT, Gemini, and Claude are products that rent you access to a closed model. On raw token price, V4 sits in a different bracket, undercutting the Western flagships by roughly an order of magnitude, though the gap narrows on finished tasks once thinking tokens are counted.
Against the current closed leaders from OpenAI, Google, and Anthropic (including Claude Opus 5), the trade is the familiar one: cost and openness versus polish, reliability across varied tasks, and a lead on the hardest agentic coding. The multimodal gap narrowed on September 10 now that V4.1 Flash reads images, but it is not closed: DeepSeek still has no audio or video input on any tier, and no image or video generation at all, where the closed leaders are full multimodal products. Against the other open-weight Chinese models, V4 is the reasoning-and-price specialist, Kimi K3 leans more agentic, and Qwen trades on breadth and multilingual coverage. For a side-by-side, our guide to the Chinese models compared puts them in one table, and the best open-source LLMs ranking places V4 in the full field.
Quirks and Gotchas Worth Knowing
A few things the benchmarks never mention still surprise people.
V4 does not reliably know it is V4. Ask it which model it is and it may answer V3; its self-report is not dependable. Do not use the model's own answer to check which version you are running; check the API model name you called instead.
Creative and open-ended work regressed slightly. Users who write fiction or do open-ended ideation report a stronger positivity bias and harder-to-steer tone than V3.2 had. It is a narrow, named-audience complaint rather than a headline flaw, but if creative writing is your use case, test before you switch.
Agent instruction-following is contested. Some builders report V4 acting outside an explicit scope in agent harnesses; others report none. The consensus fix is architectural: give it a clear orchestrator and tight tool definitions rather than trusting a long freeform instruction.
R2 still has not shipped. The reasoning model people keep asking about, DeepSeek-R2, was widely expected in 2025 on the back of press reports and has not landed; V4's built-in thinking mode is DeepSeek's answer for now. Treat R2 as a rumor until a model card exists.
What This Means for Getting Cited by AI
Come back to the opening. The reason those AI assistants gave conflicting, mostly wrong answers about V4 is not that V4 is obscure; it is a widely covered launch. It is that the assistants are only as current as the sources they can reach, and most of them had not caught up.
That is the whole game for anyone who wants to be represented accurately by AI. When a model, a product, or a fact is new, the engines fall back on whatever stale material they can find. In practice, getting quoted correctly comes down to the unglamorous disciplines this page tries to model: date your claims, cite each number to its source, put the direct answer next to the heading, and re-check the volatile facts on a schedule. That is the foundation of generative engine optimization.
Stale answers come from stale or unreachable sources, so the first move is making sure the engines can even reach and parse your pages. Run a free AI Readiness check to see where the AI crawlers get blocked or trip up on your site before the next launch makes the question urgent again.
Frequently Asked Questions
Is DeepSeek V4 out yet, or is it a preview?
It is out. V4-Pro reached general availability on August 13, 2026, ending a preview that ran from April 24. Explainers and AI answers that still call it a preview are out of date, and so is DeepSeek's own V4-Pro model card, which still carries preview wording.
Should I use V4.1 Flash or V4 Pro?
Start with Flash for almost everything: chat, extraction, summarization, high-volume agent loops, most coding, and now basic image input. Move to Pro only for hard reasoning, complex multi-step analysis, or demanding code, where the quality gain is worth the roughly 3 to 4 times higher output cost, a wider gap than before Flash's September 10 price cut.
How much does DeepSeek V4 cost per month?
The app is free. On the API your bill tracks your token volume, so the honest answer is to work it out from the table above: multiply your monthly input and output tokens by the Flash rates, and remember thinking mode adds billed reasoning tokens on top. Most individual use lands in a few dollars a month and scales from there; Pro runs about 3 to 4 times Flash for the same volume. Our DeepSeek pricing guide has worked examples. Cache hits and turning thinking off for simple tasks move the bill most.
Is DeepSeek V4 about to get more expensive?
Flash actually got cheaper. On August 16, 2026, DeepSeek replaced its flat all-day rate with a peak/off-peak split, and on September 10, 2026, it replaced the Flash model itself: V4.1 Flash now runs $0.15 input / $0.60 output per million tokens off-peak, down from V4-Flash's $0.22 / $0.66, with peak hours (01:00-04:00 and 06:00-10:00 UTC, Monday to Friday) exactly doubling every figure. V4-Pro did not move; it still runs $0.66 / $1.98 off-peak, and DeepSeek reversed an earlier plan to fold it into the cheaper Flash tier, so it continues as its own paid option. DeepSeek's pricing has moved three times in 2026, so re-check the official page before committing a budget.
Why is my DeepSeek bill higher than the sticker price?
Almost always because thinking mode is on by default and its reasoning tokens bill at the output rate, even though you never see them. Turn thinking off for routine tasks, and structure prompts to reuse a common prefix so more tokens hit the cheaper cache-hit rate.
I used deepseek-chat, deepseek-reasoner, or the old deepseek-v4-flash. What do I switch to?
deepseek-chat and deepseek-reasoner retired on July 24, 2026 and now fail outright; they were replaced by deepseek-v4-flash and deepseek-v4-pro. Of those two, only deepseek-v4-flash changed again: as of September 10, 2026, it and deepseek-v4-flash-vision-exp are temporarily routed (DeepSeek's own term) to the current model, deepseek-flash (V4.1 Flash), at its new lower price. deepseek-v4-pro was not retired and did not change. Call deepseek-flash directly in new code. Note that Flash's thinking mode is not the same as Pro-level reasoning; if you want Pro specifically, call deepseek-v4-pro.
Does DeepSeek V4 support image input now?
Yes, but only on Flash. V4.1 Flash, released September 10, 2026, is the first DeepSeek Flash-tier model with native vision, accepting images alongside text. V4-Pro still does not accept images. The earlier experimental V4-Flash-Vision-Exp build has been retired and folded into V4.1 Flash's native support.
What is the cheapest way to use DeepSeek V4?
The direct DeepSeek API, not a reseller. OpenRouter and similar marketplaces add their own margin on top of DeepSeek's rates. Going direct plus earning cache hits is the lowest-cost path.
Is the 1M-token context window real?
Yes, but it is lossy. The compression that makes a million tokens affordable means detail from early in a long prompt gets summarized, so the model can seem to ignore instructions placed at the top. Put critical instructions near the end and repeat anything that must hold.
Can I use DeepSeek V4 at work?
Through the hosted API or app, your data goes to servers in China, which many companies and regulated industries prohibit. The MIT-licensed open weights let you self-host instead, keeping data in-house, which is the usual path for sensitive work.
Is DeepSeek V4 open source?
The weights are open under the MIT License, so it is open-weight and free to download, run, and fine-tune. That is not the same as fully open source, since the training data and pipeline are not released.
What happened to DeepSeek R2?
It has not shipped. R2 was expected in 2025 and remains unreleased; V4's built-in thinking mode is DeepSeek's current reasoning offering. Treat any R2 claim as a rumor until a model card exists.
Sources
- DeepSeek API Models & Pricing (current rates, model names, vision support) - DeepSeek, verified live September 17, 2026 -
api-docs.deepseek.com/quick_start/pricing - Change Log (V4.1 Flash launch, name retirements, V4-Pro continuance) - DeepSeek API Docs -
api-docs.deepseek.com/updates - Introducing DeepSeek-V4.1-Flash (architecture, benchmarks, release announcement) - DeepSeek, September 10, 2026 -
deepseek.com/news/deepseek-v4-1-flash - DeepSeek AI Released DeepSeek-V4.1-Flash with 1M Context, FP4 KV Cache, and Cross-Layer Attention Reuse (independent technical writeup, params, benchmark table) - MarkTechPost, September 10, 2026 -
marktechpost.com/2026/09/10/deepseek-ai-released-deepseek-v4-1-flash-with-1m-context-fp4-kv-cache-and-cross-layer-attention-reuse - DeepSeek V4.1 Flash (independent Intelligence Index score) - Artificial Analysis -
artificialanalysis.ai/models/deepseek-v4-1-flash - DeepSeek-V4-Pro model card (architecture, parameters, vendor benchmarks, license) - DeepSeek on Hugging Face -
huggingface.co/deepseek-ai/DeepSeek-V4-Pro - DeepSeek-V4 technical report (hybrid attention, long-context efficiency) - arXiv -
arxiv.org/abs/2606.19348 - CAISI Evaluation of DeepSeek V4 Pro (independent benchmarks, frontier-lag finding) - NIST, May 2026 -
nist.gov/news-events/news/2026/05/caisi-evaluation-deepseek-v4-pro - DeepSeek V4 Pro - Intelligence, Performance & Price Analysis (independent index) - Artificial Analysis -
artificialanalysis.ai/models/deepseek-v4-pro - We Tested DeepSeek V4 Pro and Flash (independent scored review) - Kilo -
blog.kilo.ai/p/we-tested-deepseek-v4-pro-and-flash - DeepSeek V4 Flash and V4 Pro in Microsoft Foundry (Western hosting, US/EU residency) - Microsoft -
techcommunity.microsoft.com/blog/azure-ai-foundry-blog/introducing-deepseek-v4-flash-and-v4-pro-in-microsoft-foundry/4515174 - Three reasons why DeepSeek's new model matters - MIT Technology Review, April 2026 -
technologyreview.com/2026/04/24/1136422/why-deepseeks-v4-matters - DeepSeek-V4-Pro community discussion (long-context and creative-writing feedback) - Hugging Face -
huggingface.co/deepseek-ai/DeepSeek-V4-Pro/discussions/179